By Karl Lehnert, Director, DevProStudio
A custom AI app can look excellent in a demo and still fail the first serious week in production. The usual cause is a test strategy built around a handful of prompts instead of the system customers actually use.
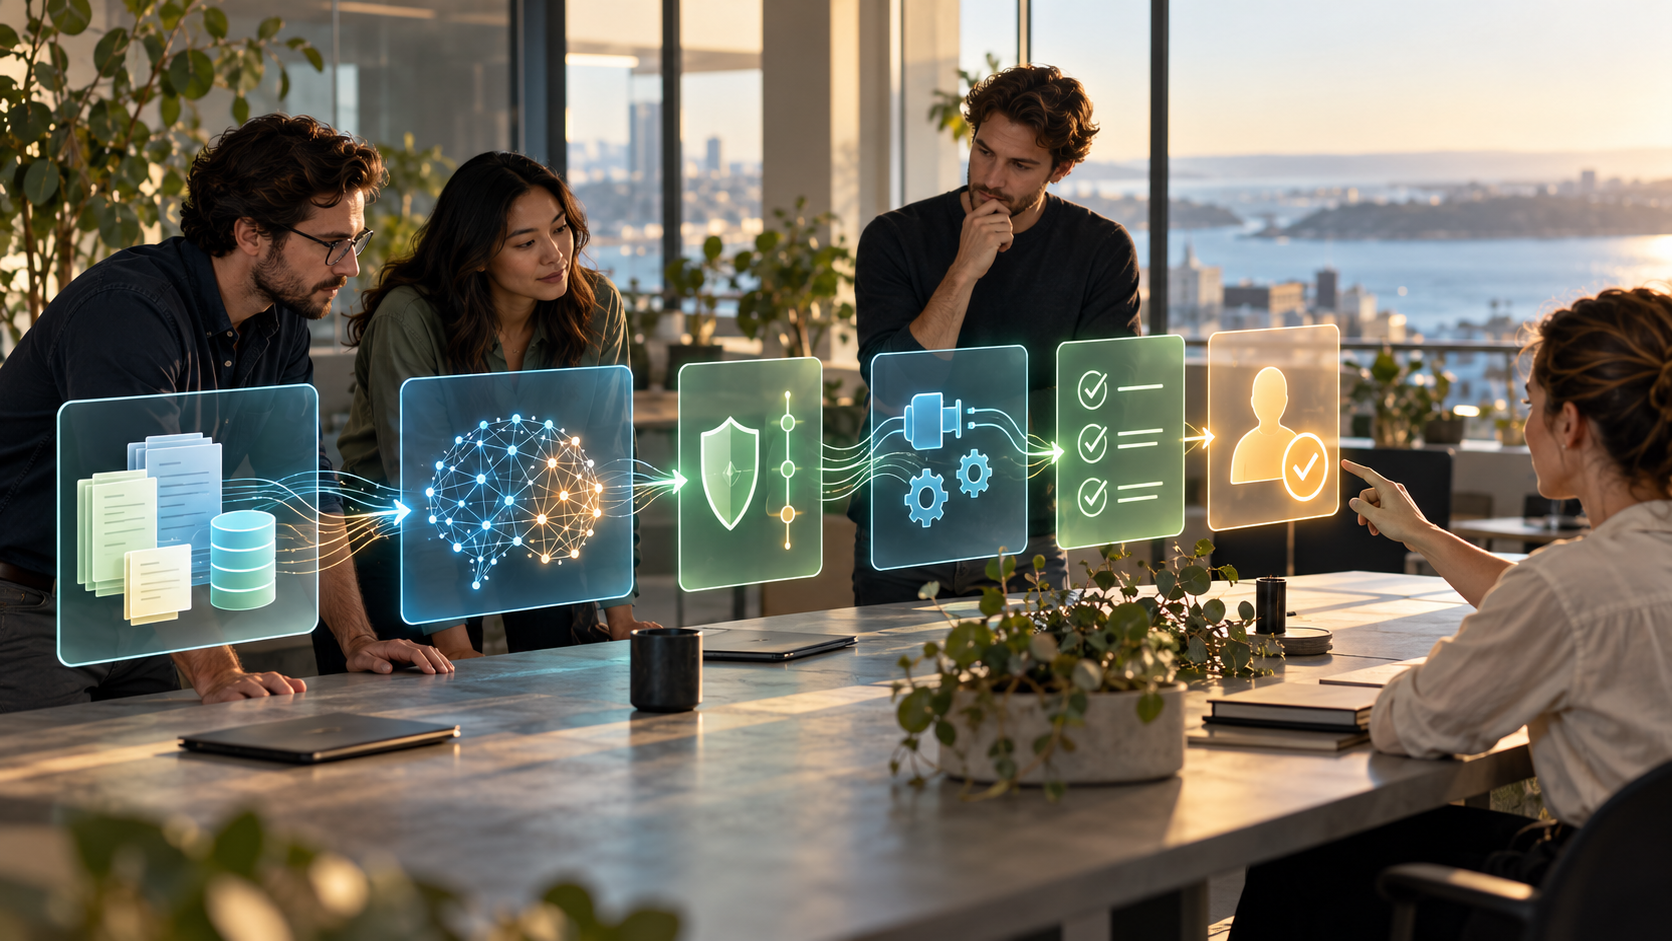
That gap matters for Australian SMEs. A model response sits inside a product boundary: uploaded documents, retrieval, business rules, tool calls, permissions, structured outputs and a human hand-off. Change any one of those pieces and yesterday’s “good prompt” may no longer prove much.
The current industry debate about prompt-only testing asks the right question. The practical answer is an AI app evaluation framework that tests behaviour from input to outcome. This builds on the move from personal workflows to shared AI products, where identity and reliability become software concerns.
Prompt checks are necessary, not sufficient
Prompt tests answer a narrow question: given this input and this model configuration, is the response acceptable? Production software raises several more:
- Did retrieval select the right source and preserve its meaning?
- Did the app refuse an action the user was not authorised to take?
- Is a structured response valid enough for the next system to consume?
- Did a tool call change the correct record, once, with an audit trail?
- Does the workflow escalate ambiguity instead of confidently guessing?
- Are latency and token cost still inside an agreed operating envelope?
OpenAI’s evaluation guidance recommends task-specific tests, logging, automated scoring where possible and continuous evaluation. The useful phrase there is task-specific. A generic “helpfulness” score cannot tell you whether an invoice-extraction app assigned GST correctly or whether a document assistant cited the supplied policy.
Our operator view at DevProStudio is simple: test the boundary, not just the brain. The model is one dependency in a software product.
The six layers of a practical evaluation framework
1. A versioned test set
Begin with 30 to 50 representative cases, not thousands of synthetic prompts. Include ordinary requests, awkward formatting, missing information, conflicting documents and attempts to cross a permission boundary. Store the input, relevant context, expected properties and risk level in version control.
Prefer properties such as “cites source section 4.2”, “returns valid JSON” or “asks for approval before sending” instead of requiring exact wording.
2. Deterministic checks
Use ordinary code wherever the answer can be checked mechanically. Validate schemas, required fields, calculations, citations, identifiers, access decisions and tool-call arguments. These tests are cheap, repeatable and easy to investigate.
Claude Code or OpenAI Codex can help generate test scaffolding, but a person who understands the process must set acceptance criteria.
3. Semantic quality checks
Some outputs need judgement: tone, completeness, relevance or whether a summary preserves an important qualification. A rubric-based model grader can scale the first pass, but calibrate it against human-reviewed examples. Keep a sample for manual review and track disagreements.
Model-on-model grading is evidence, not an oracle; related models can share blind spots.
4. Adversarial and safety tests
Test prompt injection, malicious documents, data exfiltration requests, oversized inputs and repeated tool calls. The OWASP Top 10 for LLM Applications is a useful catalogue of failure classes, including prompt injection, sensitive information disclosure, excessive agency and unbounded consumption.
5. End-to-end workflow tests
Run cases through retrieval, model, tools and downstream systems in a safe test environment. Verify both the visible answer and the side effects. A polished response paired with the wrong CRM update is a failed test.
For autonomous actions, test idempotency: retrying after a timeout must not create two invoices, two emails or two tickets. Also test the stop conditions. The safest agent is often the one that knows when to hand control back.
6. Production signals
Offline tests cannot capture every real request. Monitor refusal rates, schema failures, tool errors, latency, cost, escalations and user corrections. Sample outputs for review using a documented process, then turn recurring production failures into new regression cases.
A complaint should become a regression test, not remain an anecdote.
A common implementation pattern
Consider a service business building an AI app to draft a scope of work from an enquiry, reference documents and a pricing catalogue. No verified client evidence was available for this article, so this is explicitly an implementation pattern—not a claimed result.
The evaluation set might include complete enquiries, vague requests, obsolete price files, contradictory attachments and a user asking for a discount outside their authority. Deterministic checks validate the output structure, catalogue identifiers and arithmetic. Semantic checks assess whether exclusions and assumptions are clear. End-to-end tests confirm that draft status is preserved and nothing is sent without approval.
A release evidence pack should contain the test-set version, model and prompt versions, failed case IDs, reviewer decision and rollback note. A simple gate requires every permission and calculation test to pass, no critical safety regression, and an agreed quality threshold. Define it before seeing results. DevProStudio’s related production delivery checklist covers the surrounding release controls.
Keep evaluation costs proportionate
Use risk-based tiers:
- On each material change: a small, high-risk regression suite.
- Before release: the full representative suite across supported models and configurations.
- On a schedule: broader adversarial tests and human quality review.
- After an incident: a new reproduction case plus related variants.
Estimate each run as test cases × model calls × retries, then add reviewer time. For a concrete budget worksheet, 50 cases run twice equals 100 calls; multiply input and output tokens by the provider’s published per-token rates, then add reviewer hours at their loaded hourly cost. Recalculate when model pricing changes.
Licensing changes the choice. Prefer a custom harness when deterministic rules, private integrations or multiple providers dominate. Prefer a managed tool when non-technical reviewers must maintain cases and its subscription costs less than the engineering time it replaces. Compare seat minimums, usage charges, data retention, SSO and export rights—not the headline monthly price. If the full suite misses the release window or budget, split it by risk rather than lowering the pass bar.
Australian privacy and security cannot be an appendix
Evaluation data is still data. Do not copy live customer records into a test set by default. The OAIC advises organisations not to enter personal information—particularly sensitive information—into publicly available generative AI tools and recommends a privacy impact assessment for high-risk uses.
Use synthetic or de-identified cases where practical, restrict evaluation logs and document retention. Check whether an overseas model provider receives personal information: APP 8 can make an Australian entity accountable for a recipient’s handling. APP 11 requires reasonable security and, subject to exceptions, destruction or de-identification when data is no longer needed.
The Privacy Act’s small-business exemption is not a blanket pass; some businesses under the turnover threshold are covered because of what they do, and contracts may go further. Use this release check:
- Does the test set contain personal or sensitive information?
- Is an overseas provider receiving it, and are APP 8 controls documented?
- Are access, retention and deletion controls sufficient under APP 11?
- Could a leak cause serious harm and require assessment under the OAIC’s Notifiable Data Breaches scheme?
NIST’s Generative AI Profile provides a useful frame across governance, mapping, measurement and management: named owners, documented high-impact failures, release gates and a response plan.
FAQ
What is AI app evaluation?
AI app evaluation is the repeatable testing of an AI product’s outputs and behaviour against defined criteria. It covers the model plus retrieval, permissions, tools, structured data, cost, latency and human escalation.
How many evaluation cases should an SME start with?
Start with roughly 30 to 50 high-value cases covering common requests and serious failure modes. Quality and coverage matter more than volume. Add cases whenever production reveals a new failure.
Can an LLM grade another LLM’s output?
Yes, rubric-based model grading is useful for scalable first-pass assessment. Calibrate it with human-reviewed examples, monitor disagreement and never rely on it alone for permissions, calculations or other deterministic rules.
When should evaluation run?
Run a small risk-focused suite on material changes, a full suite before release, broader adversarial tests on a schedule and a reproduction test after every incident.
Turn demos into dependable software
The goal is evidence that the app still performs the job, respects its boundaries and fails safely after each change.
DevProStudio designs custom AI apps and evaluation workflows around real business systems. If your prototype needs production-grade release gates, talk with DevProStudio.
About the author: Karl Lehnert is Director of DevProStudio. This article draws only on the engineering approach and public sources cited above; no unverified client outcome is claimed.